This guide explains how to assess a Talkdesk Chatbot for real-world customer service outcomes. It outlines objective background on conversational AI in contact centers, how bot interactions integrate with routing, knowledge, and compliance workflows, and what to verify before rollout. You’ll also find practical evaluation steps, requirements, and FAQs to support decision-making.
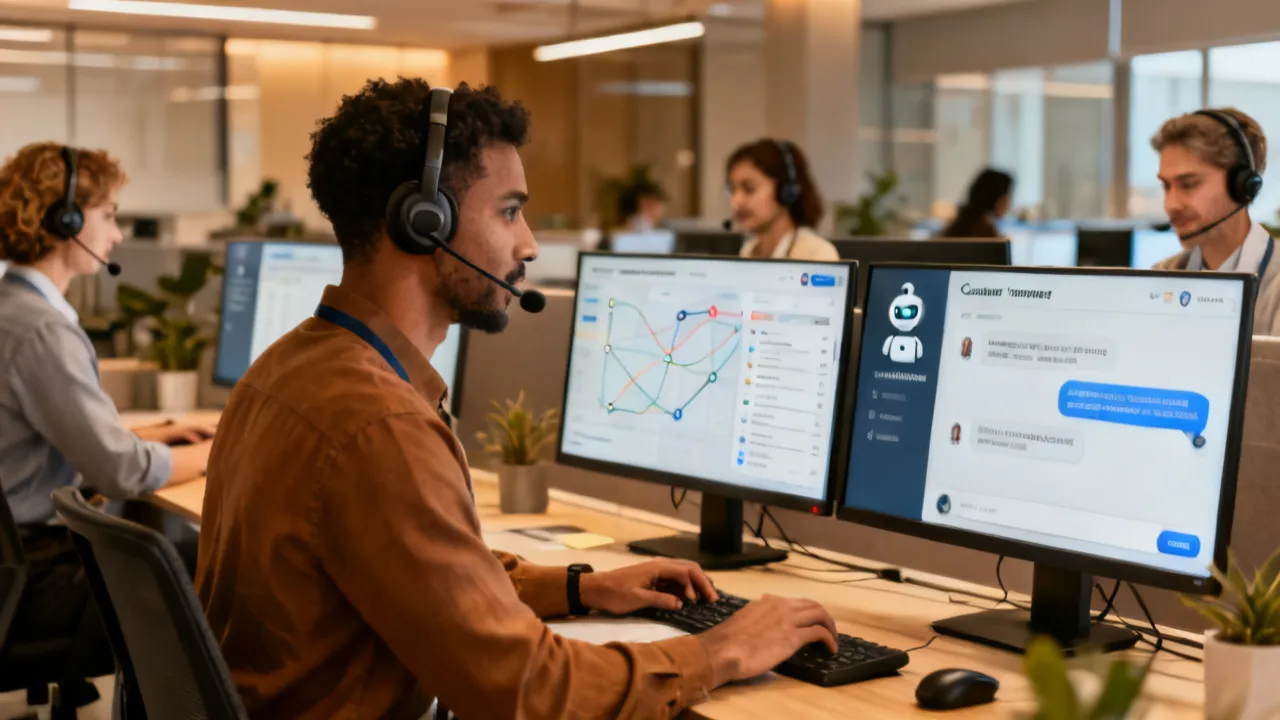
A Talkdesk Chatbot can improve customer experience by handling routine inquiries, reducing handle times, and supporting consistent responses—but only if it’s evaluated against your operational goals. Start by confirming how the bot will connect to your existing contact center stack (telephony, CRM, knowledge base, and ticketing), how it escalates complex cases to agents, and how performance will be measured in a way that reflects your service standards. For many teams, the very important question is not “Does the bot work?” but “Does the bot behave reliably under the same conditions where customers actually contact you?”
To answer that second question, teams should test the bot in realistic conditions: the kinds of questions that appear during peak volume, the messy phrasing customers use when frustrated, and the edge cases that don’t appear in clean test scripts. A chatbot can appear successful in a demo while still failing in production because it was trained or configured against idealized inputs, incomplete knowledge sources, or insufficient escalation logic. In practice, evaluation must therefore examine both the conversational experience and the operational mechanics behind it.
From an industry-expert perspective, successful deployments typically share three characteristics: (1) clear conversation design tied to real intents, (2) disciplined integration with live operational systems, and (3) governance that ensures safe, auditable responses. This is especially relevant when your brand voice, privacy expectations, and regulatory constraints demand consistency. The closer the chatbot is to production workflows—especially those that retrieve account data, update case records, or create tickets—the more evaluation must focus on controls, not just content quality.
In other words, when you evaluate a Talkdesk Chatbot, you’re not simply assessing an application. You’re assessing a service behavior that spans multiple systems: an understanding layer (intents and conversation logic), an information layer (knowledge sources and policies), an action layer (ticket creation, updates, and data retrieval), and an assurance layer (monitoring, auditing, and escalation). If any of these layers is weak, the bot may still “answer,” but your customers may experience it as unreliable, unsafe, or unhelpful.
Conversational AI has evolved from simple FAQ bots into workflow-driven assistants that can resolve common requests and assist agents with context. In customer support environments, chatbots generally sit alongside other channels—voice, email, live chat, and messaging—while working toward unified customer journeys. A Talkdesk Chatbot, specifically, is positioned to align with contact-center operations by leveraging conversational flows and system integrations that help support teams manage inbound requests more effectively.
Historically, organizations implemented chatbots primarily to reduce ticket volumes or to deflect questions that were already answered in help articles. Over time, however, the highest value has shifted toward “service orchestration”: the bot identifies the customer need, fetches the right information, performs appropriate actions (like checking an order status or initiating a cancellation workflow), and only escalates when it genuinely cannot resolve the matter safely or confidently. This is where modern implementations can help agents by providing pre-validated context and reducing repetition.
However, the value of any chatbot depends on the quality of underlying resources: knowledge content, intent definitions, escalation rules, and monitoring practices. Without those foundations, chatbot responses can become inconsistent, customer satisfaction can drop, and agents may still need to rework issues already “handled” by automation. A common real-world failure mode is “false containment,” where the bot provides an answer that seems relevant but doesn’t actually resolve the customer’s underlying need, leading to follow-up contacts, frustrated escalations, or even churn.
Another common issue is “integration brittleness,” where the bot relies on upstream systems that behave differently than expected—such as delayed order status updates, permissions restrictions, API outages, or mismatched identifiers between CRM and commerce platforms. If evaluation doesn’t include operational testing (latency, permissions, error handling), the bot may fail silently or produce partial responses. In customer service, partial responses can feel worse than no responses because customers believe the bot is “almost” helping.
Finally, modern customer service expectations include omnichannel continuity. Even if the chatbot is only deployed in one channel, customers may switch channels when they’re dissatisfied or when the conversation becomes complex. Evaluation must therefore consider cross-channel behavior and handoff continuity: the bot’s summary, extracted details, and recommended next steps should remain consistent when an agent takes over or when the case is moved into ticketing and CRM.
Use the following criteria to evaluate a Talkdesk Chatbot in a structured way. Consider each item as a “gate” that must be passed before scaling. The priority order matters because failures compound: weak integration undermines both safety and measurement; weak escalation ruins customer experience; poor knowledge governance makes performance metrics misleading.
When you run the checklist as gates, you can avoid the common trap of approving a chatbot based on early pilots that only exercise the “happy path.” Gate-based evaluation forces the team to prove the bot’s behavior in the scenarios that actually create cost, risk, and dissatisfaction.
Integration readiness also includes operational concerns: how the bot behaves when upstream services are slow or temporarily unavailable. A well-designed bot should have clear fallbacks (for example, “I can’t reach the order system right now; I can still start a ticket” or “Let me connect you to an agent”). Evaluation should test degraded modes on purpose rather than hoping upstream systems never fail.
Finally, integration readiness should be evaluated with security expectations in mind. Even if the bot is only “reading” data, it must be permissioned appropriately. A chatbot that can retrieve too much information or logs data in ways that violate retention policies can create serious compliance risk. So integration readiness includes both functional access and security boundaries.
Escalation design should also address timing. Some bots escalate immediately upon low confidence; others attempt multiple turns to clarify. Evaluation should test the user experience impact of each approach: if the bot asks too many clarifying questions, the customer may lose patience; if it escalates too quickly, it may fail to reduce workload. The ideal approach typically balances confidence with user effort, and it is tuned based on analytics from pilot interactions.
Another aspect is escalation routing: which agent group or queue should receive the case? If routing is wrong, the case may bounce between teams, creating delays and rework. Evaluation should confirm that the bot escalates into the correct operational workflow and not simply into a generic “support” queue.
Intent quality also includes classification accuracy and robustness. Many organizations over-focus on “top intent” accuracy and ignore “multi-intent” reality: customers often combine issues in a single message (“My order is late and I was charged twice”). A strong chatbot design can either handle multi-intent flows or confidently split the conversation into steps that address the most urgent issue first, while still tracking unresolved secondary needs for escalation.
Evaluation should also examine the bot’s handling of ambiguity. For example, a customer may reference a “return” but mean “exchange” or “refund,” or they may reference “support” but mean “warranty claim.” The bot should either ask a targeted clarifying question or escalate when clarification can’t safely be achieved.
Another important dimension is KB retrieval quality: if the bot uses semantic search, evaluation must test whether it retrieves the correct article and whether it grounds responses in retrieved content. Even if the language sounds correct, grounding is essential to avoid hallucinations or unsupported claims. In production, customers may rely on the bot’s statements; therefore, your evaluation should confirm that the bot cites only content that is known, current, and approved.
Safety evaluation should also include prompt injection and misuse scenarios where users attempt to manipulate the bot to reveal hidden instructions, bypass safety rules, or access restricted systems. Even if the chatbot is not expected to face adversarial users frequently, evaluation should confirm that it can handle “trick” inputs gracefully without system leakage.
Privacy expectations should also consider data minimization. When possible, the bot should request only the minimum information needed to help the customer. Evaluation should check whether the bot requests personal data unnecessarily or repeats requests in a way that increases data exposure. Additionally, the bot’s logging policy should avoid storing sensitive data in plain text longer than required.
Finally, compliance evaluation should include jurisdictional considerations: data residency requirements, retention windows, and consent requirements for communication methods. If your organization operates across regions, you should ensure the bot’s behavior aligns with local regulations.
Measurement should also define what success looks like for each intent. For instance, “order status” may be considered resolved when the bot provides accurate tracking and expected delivery window. “Refund request” might be resolved when the bot gathers required details and initiates a workflow—though the final approval may require an agent. Therefore, evaluation should include task completion criteria, not just “bot ended conversation.”
Additionally, measurement must include escalation appropriateness. A bot that escalates too often can increase workload; a bot that escalates too rarely can provide incorrect guidance. Evaluation should assess escalation accuracy via sampling and QA review. Ask how the supplier supports this process.
Finally, measurement should address user satisfaction and sentiment. Customer dissatisfaction may not always show up in explicit surveys; it can appear through repeated contacts, negative sentiment keywords, or increased refund/churn signals. Evaluation should confirm whether you can capture and analyze these signals responsibly.
Teams often ask about price first, but the better approach is to estimate total value and risk rather than only the headline number. While exact pricing varies by contract, plan scope, and volume, you can still structure a cost evaluation that remains objective.
When reviewing Talkdesk Chatbot commercial terms, ask for clarity on:
Cost evaluation should also include operational impact costs. For example, if the chatbot reduces ticket volume but increases agent handle time due to poor handoff summaries, the net savings can disappear. Conversely, if the chatbot provides agent-ready context and reduces repetition, it can create measurable savings that should be reflected in ROI analysis.
Another pricing-related consideration is the cost of “engineering constraints.” Some vendors may offer flexibility but require specific architecture patterns. If your team needs to integrate with multiple systems, you may incur additional implementation effort to match the vendor’s integration expectations. Evaluation should include a technical discovery phase with clear deliverables and timelines, so pricing reflects the true scope.
It’s also important to ask about costs for new use cases after launch. Many teams start with one or two intents and then expand. The pricing contract should clarify whether adding intents requires additional licensing, additional professional services, or any restrictions. Your evaluation should ensure you won’t face unexpected costs when scaling.
Note: If you intend to request exact quotes from suppliers, do so through official procurement channels. This protects procurement accuracy and ensures you receive terms aligned to your contract and region.
Even when a platform is capable, implementation quality often determines real customer outcomes. If you’re selecting a supplier for a Talkdesk Chatbot program (including the platform provider, implementation partner, or systems integrator), request evidence for delivery maturity.
Ask the supplier to provide:
In addition to these items, request operational readiness documentation: what happens in incidents, how alerts are configured, who monitors health metrics, and what service level expectations exist (e.g., response latency, uptime, integration failures). A chatbot that answers incorrectly can be risky, but a chatbot that fails silently and leaves customers stuck is also a major customer experience issue. Evaluation should include incident handling expectations.
Also ask about analytics capabilities and data access. Teams often discover late that they cannot easily export transcripts or analyze intent breakdown. For evaluation to be meaningful, you must be able to observe performance: what users asked, what the bot answered, when it escalated, and how outcomes changed over time. Supplier selection should include confirming that you can access needed reporting and that data is available in a format your team can work with.
Finally, evaluate the supplier’s approach to knowledge integration and content maintenance. The supplier should explain how knowledge updates propagate into bot responses and how they avoid breaking conversation flows when policies change. Look for explicit change management practices, not just “we’ll update the KB.”
From observed industry patterns, customer support chatbots tend to deliver the very value when questions are frequent, policy-driven, and answerable through structured data or well-maintained knowledge. A Talkdesk Chatbot commonly performs strongly in scenarios such as:
Conversely, the highest risk areas are often emotionally charged disputes, complex billing edge cases, and requests requiring nuanced judgment. In those areas, escalation and agent-assist capabilities matter more than automation alone. For example, a bot can gather the details needed for a billing investigation and prepare a structured case, but it should not approve refunds or deny claims without the appropriate authority. Evaluation should therefore classify each potential use case by “automation maturity”: low-risk informational tasks, medium-risk workflow initiation tasks, and high-risk decisions requiring human review.
It can also help to distinguish between “customer expectation tasks” and “business decision tasks.” Customer expectation tasks are those where users primarily want information (“When will my order arrive?” “How do I reset my password?”). Business decision tasks are those where the company must decide (“Approve this exception?” “Waive this fee?” “Confirm eligibility?”). Strong bot programs prioritize expectation tasks initially and build toward business decision tasks only after governance and auditability are mature.
Additionally, chatbot performance depends on channel and context. A bot may perform better in web chat because users can provide screenshots or additional text and the conversation can be multi-turn. Voice or shorter messaging channels may reduce the bot’s ability to gather details, increasing escalation frequency. Evaluation should therefore include channel-specific testing and not assume performance will transfer across channels automatically.
Finally, use-case mapping should incorporate operational feasibility: does your team have the ability to resolve cases created by the bot within required timeframes? If the bot creates tickets for cancellations, your operations team must have workflows ready to handle those requests. Otherwise, customers will experience delays that the bot’s automation cannot fix.
Even without a specific city or country in the keywords, localization should still be treated as a functional requirement. Customers “nearby” may expect certain communication styles, help-center terminology, and culturally appropriate phrasing. For example:
If your support team interacts with customers in multiple languages, ensure the chatbot’s knowledge sources are localized, not merely translated—intent classification and content mapping often require separate tuning. A common failure mode is to translate content without updating intent definitions. This can lead to wrong classifications, because intent detection relies on linguistic cues that differ across languages. Evaluation should therefore test end-to-end for each language, including escalation and policy responses.
Localization also affects compliance messaging. Privacy consent phrases, identity verification instructions, and policy disclosures must be culturally and legally appropriate for each region. For regulated topics, a “literal translation” may not satisfy legal requirements. Evaluation should coordinate with legal/compliance for localized content approvals.
Tone calibration should also consider brand personality and customer sentiment. Customers in certain industries may expect a more formal tone (e.g., finance or healthcare), while others may tolerate informal messaging. However, even in informal contexts, tone must remain respectful. Evaluation should include sampling of transcripts across different user sentiment levels to ensure the bot never escalates conflict through wording.
Finally, localization includes fallback behavior. If the bot cannot confidently answer in a given language, it should either ask a clarification question in that language or offer a transfer to a human who can help. The bot should avoid switching languages abruptly or responding with partially translated content that can confuse users.
The following guide is designed as a practical method to move from concept to controlled rollout. It reflects common contact-center evaluation practices used by implementation teams and service owners.
In addition, create an internal “conversation design spec” so the bot’s behavior is documented. This spec should include: intents and utterances, required fields, response templates, escalation reasons, privacy statements, and acceptance criteria. When this documentation exists, evaluation becomes repeatable and audit-friendly.
Another useful practice is to establish a “red team” or adversarial test set. It contains inputs that attempt to break the bot: requests for disallowed data, prompt injection attempts, and combinations of unrelated issues. Even a small test set can reveal safety weaknesses early. Evaluation should treat these tests as part of the quality gate, not as optional extras.
Also consider how you will handle knowledge conflicts. If two articles contradict (e.g., different return policy terms for different product categories), the bot must choose the correct policy based on context. Evaluation should include scenarios where multiple policies might apply and confirm that the bot resolves the conflict deterministically or escalates when it cannot.
Finally, plan for stakeholder alignment. Evaluation should involve not only IT and the chatbot team, but also support operations, QA, legal/compliance, and product owners. Each group should have clear responsibilities and sign-off points. Without cross-functional involvement, a bot may pass technical tests but fail operational acceptance.
Before production use, set baseline conditions to reduce operational risk. These requirements are written as a checklist you can align internally with IT, support operations, legal/compliance, and product owners.
Beyond these baseline conditions, successful rollouts typically require operational playbooks. These playbooks define what happens if the bot experiences issues: upstream integrations fail, the knowledge source becomes unavailable, or the bot begins misclassifying intents due to shifts in customer language. A playbook should outline who gets notified, how quickly the bot is paused, and how to restore correct behavior.
Operational readiness should also include “customer communication” guidelines. If the bot cannot help due to system issues, what is the message to the customer? The fallback message should be honest, non-alarming, and action-oriented. If the bot is paused, customers should not be left in a broken conversation loop. Evaluation should test user experience during such transitions.
Another condition is eligibility and constraints. Decide which customer segments and which types of requests are eligible for bot handling. For example, certain accounts might require additional verification steps, or high-risk disputes might always require human assistance. Eligibility rules reduce risk by limiting the bot’s exposure in early phases.
Finally, ensure that agent teams are trained to interpret bot-created artifacts. If the bot extracts fields, initiates workflows, or creates tickets, those outputs must be standardized so agents can act quickly. A bot can only reduce workload if the downstream workflow can absorb and benefit from the information it provides.
| Dimension | What “good” looks like | What to ask suppliers |
|---|---|---|
| Conversation scope | Bot handles a prioritized subset of intents end-to-end with safe fallbacks. | “Which intents are included initially, and how do you measure containment quality?” |
| Integration coverage | Bot can retrieve (and only update when approved) the data needed for resolutions. | “What systems can you integrate with, and what are your validation steps?” |
| Handoff behavior | Customers do not repeat themselves; agents receive a useful conversation summary. | “How do you ensure escalation triggers and agent context mapping are reliable?” |
| Knowledge governance | Content refresh is scheduled; answers map to versioned sources. | “Who owns knowledge updates, and how is content QA enforced?” |
| Compliance readiness | Privacy controls, consent handling, and audit logs are clearly defined. | “What security practices and compliance documentation can you provide for our use case?” |
| Performance measurement | Metrics include resolution quality and escalation appropriateness, not only volume. | “What analytics are available, and how do you interpret bot performance risks?” |
| Rollout method | Controlled pilot before broader release, with documented acceptance criteria. | “What pilot plan do you recommend and what thresholds must be met?” |
To make the comparison table actionable, you can turn each row into an internal acceptance checklist. For instance, for “integration coverage,” your internal gate might require evidence that permissions are correct for at least 10 representative customer scenarios (including missing or incorrect identifiers). For “knowledge governance,” your gate might require proof that knowledge updates are scheduled and that you have a documented approval workflow.
Similarly, “handoff behavior” can be converted into measurable criteria: in a sampled set of escalations, agents should report that customer context is provided and that required details are prefilled. You can measure this via QA forms from agents or via observed reduction in agent time-to-resolution during pilot periods.
Finally, “performance measurement” should specify reporting granularity. Ask whether you can segment performance by intent, channel, language, and customer segment. Without segmentation, you may see overall improvements while missing that one language or one product category experiences poor accuracy or inappropriate escalations.
To keep evaluation grounded in commonly reported industry practice, the discussion above aligns with widely cited frameworks for customer contact automation and conversational AI governance. For background on how conversational systems are measured and managed in enterprise contexts, readers may refer to:
Note: Specific chatbot performance metrics vary by industry, intent scope, and knowledge quality. Avoid benchmarking yourself against inflated claims; instead, validate using pilot traffic and your own success criteria.
In addition to high-level frameworks, evaluation often benefits from operational evidence. For example, request examples of QA scorecards, escalation sampling plans, and governance documents used in similar deployments. These artifacts provide stronger evidence than marketing claims and help you assess whether the supplier can support continuous improvement after launch.
Another evidence source is historical performance data from your own contact center. You can compare outcomes of bot-handled intents to historical “human-only” outcomes, adjust for differences in traffic mix, and isolate patterns where bot performance is strong or weak. This internal comparison often reveals where additional knowledge grooming, conversation redesign, or escalation tuning is needed.
Finally, consider customer journey mapping as evidence. Evaluate where the chatbot sits in the journey: is it at the beginning of contact, or after customers already tried other options? If customers reach the bot after a failed self-serve attempt, they may be more frustrated and more likely to escalate. Your evaluation should incorporate this context so you interpret success metrics correctly.
A Talkdesk Chatbot is typically designed to support conversation-driven customer service within a contact-center workflow. Unlike simple FAQ bots that provide static answers, a well-implemented chatbot can use intent recognition, access relevant customer or service data, and escalate to agents when needed—depending on your integration and governance design.
To evaluate the difference in practice, teams should ask how the bot transitions from “answering” to “acting.” For example, does it simply quote policy, or can it check order status and create a case? Does it confirm identity and route requests appropriately? A basic FAQ bot might be fine for informational scenarios, but it rarely provides the operational value that a workflow-driven chatbot can deliver when integrated with CRM, ticketing, and knowledge governance.
Focus on resolution quality rather than only containment rate. In a pilot, compare: (1) escalation appropriateness, (2) whether bot-handled issues lead to fewer follow-up contacts, and (3) whether agents receive useful context. Also monitor whether deflection causes repeat inquiries due to incomplete resolution.
It also helps to measure time-to-resolution for escalated cases. If the bot’s handoff provides structured context, escalated cases should be faster to resolve than similar cases without bot involvement. Conversely, if agents spend extra time correcting incorrect bot actions, the workload might increase. Pilot analysis should include both “bot-contained” and “bot-escalated” outcomes.
Start with high-frequency, policy-driven intents that map cleanly to knowledge content and structured data. Avoid complex disputes or requests requiring nuanced human judgment in the first stage. Expand only after transcripts show correct behavior and safe fallbacks.
Pilot scope should also include representative edge cases. If you test only the top phrasing variations, you may not discover where the bot fails. A well-designed pilot includes: ambiguous requests, missing data scenarios, and conflicting policy situations. This ensures that evaluation results are predictive of real-world behavior.
Typical requirements include privacy and consent handling, access control, audit log availability, data retention rules, and restrictions on what the bot can disclose. The exact expectations depend on your industry and jurisdiction, so align early with your compliance stakeholders.
Legal/compliance requirements often extend to how you handle user data in logs and how long data is retained. They may also require that the bot’s refusal messages are consistent and that sensitive information is masked. Evaluation should explicitly request evidence of these controls and the ability to audit them.
Define escalation triggers (e.g., low confidence, missing information, sensitive topics), then ensure handoff includes a short conversation summary and any relevant extracted data. The agent experience should minimize repetition and reduce time-to-resolution.
Also define “escalation etiquette.” Customers should not feel abandoned. The bot should acknowledge the issue, explain the reason for escalation in an empathetic way, and provide confidence that the agent will have the context. Evaluation should test these messages across different user sentiment levels.
Yes. “Nearby” audiences still differ in preferred phrasing, help-center terminology, and tone expectations. Localization should cover language variants, customer terminology, and accessibility requirements—not only translation.
In practical terms, localization affects how intents are detected. Even closely related languages or regional variants can require separate intent training and content mapping. Evaluation should confirm that the bot’s confidence and escalation thresholds are appropriate for each language variant.
Establish content ownership and a review cadence. Implement change management so that updated policies and product information propagate into the bot’s decision logic and knowledge retrieval. Periodically sample transcripts to detect drift or outdated responses.
Knowledge freshness should be a measurable operational metric. For example, critical policy articles should be updated within defined SLA windows. Bot performance monitoring should include alerts for likely staleness: rising “I tried that but it didn’t work” feedback, increased escalation rates for certain intents, or transcripts referencing outdated policy language.
Any automation introduces operational and customer experience risk if not governed. The risk is manageable when you apply governance practices: safe fallbacks, controlled integration, monitoring, and auditability. The goal is reliability under real-world conditions, not maximal automation coverage.
Risk management is not only about preventing incorrect answers; it’s also about preventing broken experiences (timeouts, infinite loops, and unclear next steps). Evaluation should therefore treat reliability, graceful degradation, and user guidance as risk controls.
A robust Talkdesk Chatbot evaluation is ultimately about accountability: measurable outcomes, integration that respects operational realities, and governance that keeps responses safe and consistent. When your team defines intent scope, confirms escalation behavior, and builds a monitoring loop for continuous improvement, the chatbot becomes an operational tool rather than an experiment.
If you’re preparing procurement or implementation discussions, treat supplier proposals as testable plans. Ask for pilot criteria, integration validation steps, and how they will support knowledge governance and compliance readiness. That approach protects both customer experience and good operational stability.
To make the decision truly defensible, ensure your evaluation artifacts are internal and retrievable: documented success metrics, pilot acceptance thresholds, QA sampling results, integration test evidence, and change management design. When decisions are challenged internally (“Why did we deploy this?” “Why did it fail?”), you’ll need evidence that ties outcomes to the work you validated.
As you move from pilot to scale, remember that the chatbot’s long-term value depends on an organizational commitment to maintenance. Technology can enable automation, but the reliability customers experience is built through disciplined knowledge governance, careful conversation design, and operational monitoring. If you invest in those foundations, your Talkdesk Chatbot can deliver meaningful improvements in customer experience while keeping risk and compliance under control.
Ultimately, the best evaluation process produces more than a go/no-go decision—it produces a roadmap. That roadmap clarifies which intents are prioritized next, what knowledge updates are required, how escalation will evolve, what thresholds will be tuned, and how measurement will mature. When that roadmap exists, the chatbot program becomes sustainable, and scaling decisions become rational rather than reactive.
Striking the Perfect Balance: Navigating Premiums and Out-of-Pocket Expenses in Senior Insurance Plans
Explore the Tranquil Bliss of Idyllic Rural Retreats
How to Make Lasting Memories at Disneyland Attractions
Affordable Phones and Plans for Seniors
Affordable Full Mouth Dental Implants Near You
Unlock the Top Kept Secrets to Finding Your Ideal Dentist for Flawless Dental Implant Results!
Discovering Springdale Estates
The Guide to Car Trading

Affordable Cell Phones Without Plans
Understanding the Concept of Ibiaeon
Dive into the groundbreaking concept of Ibiaeon, a theoretical model that combines technological advancements with philosophical perspectives. Ibiaeon represents a unique intersection where innovation meets ethical considerations, aiming to offer sustainable solutions for future societal challenges. This guide presents a deep analysis of the possibilities and implications associated with Ibiaeon.
Understanding the Sage Cte Platform
Sage Cte is a powerful software offering comprehensive solutions for businesses across various industries. This article delves into its capabilities, exploring its integration with different systems, cost implications, and the significance of choosing the right supplier. By understanding Sage Cte, businesses can make informed decisions for optimal operational efficiency and competitive advantage.
An In-Depth Look at Salesforce
Salesforce is a transformative cloud-based customer relationship management (CRM) platform that empowers businesses to streamline their sales, service, and marketing efforts. Known for its robust suite of tools and global reach, Salesforce has become an industry standard in CRM solutions, providing businesses with unparalleled insights and automation capabilities essential for growth and customer retention.
Seamless Integration of Sagepay and Salesforce
This guide highlights the integration of Sagepay with Salesforce, emphasizing the importance of harmonizing payment processing with customer relationship management. Sagepay offers secure online payment solutions, while Salesforce provides comprehensive CRM services, both popular among businesses seeking efficiency. Explore how they complement each other for enhanced business functionality.
Plansource BambooHR: Expert HR Platform Comparison Guide
Plansource BambooHR helps organizations standardize HR workflows with modern recruiting, onboarding, and people analytics. This guide explains what the keywords typically refer to in HR technology contexts, outlines how businesses evaluate these platforms, and provides an expert comparison framework so HR leaders can make informed sourcing decisions based on requirements, implementation scope, and total cost considerations.
Integrating Sagepay with Salesforce
Integrating Sagepay with Salesforce streamlines business operations by combining sophisticated CRM capabilities with a secure payment gateway. This fusion allows businesses to efficiently manage customer relations and transactions within one seamless framework. Sagepay ensures secure and swift payments, while Salesforce aids in comprehensive customer relationship management, enhancing overall operational productivity and customer satisfaction.